NexusNote
Workspace-based knowledge management for students and knowledge workers, with a RAG-powered AI assistant.
- Status
- Live
- Role
- Full Stack Developer
- Team
- Solo
- Timeline
- Ongoing
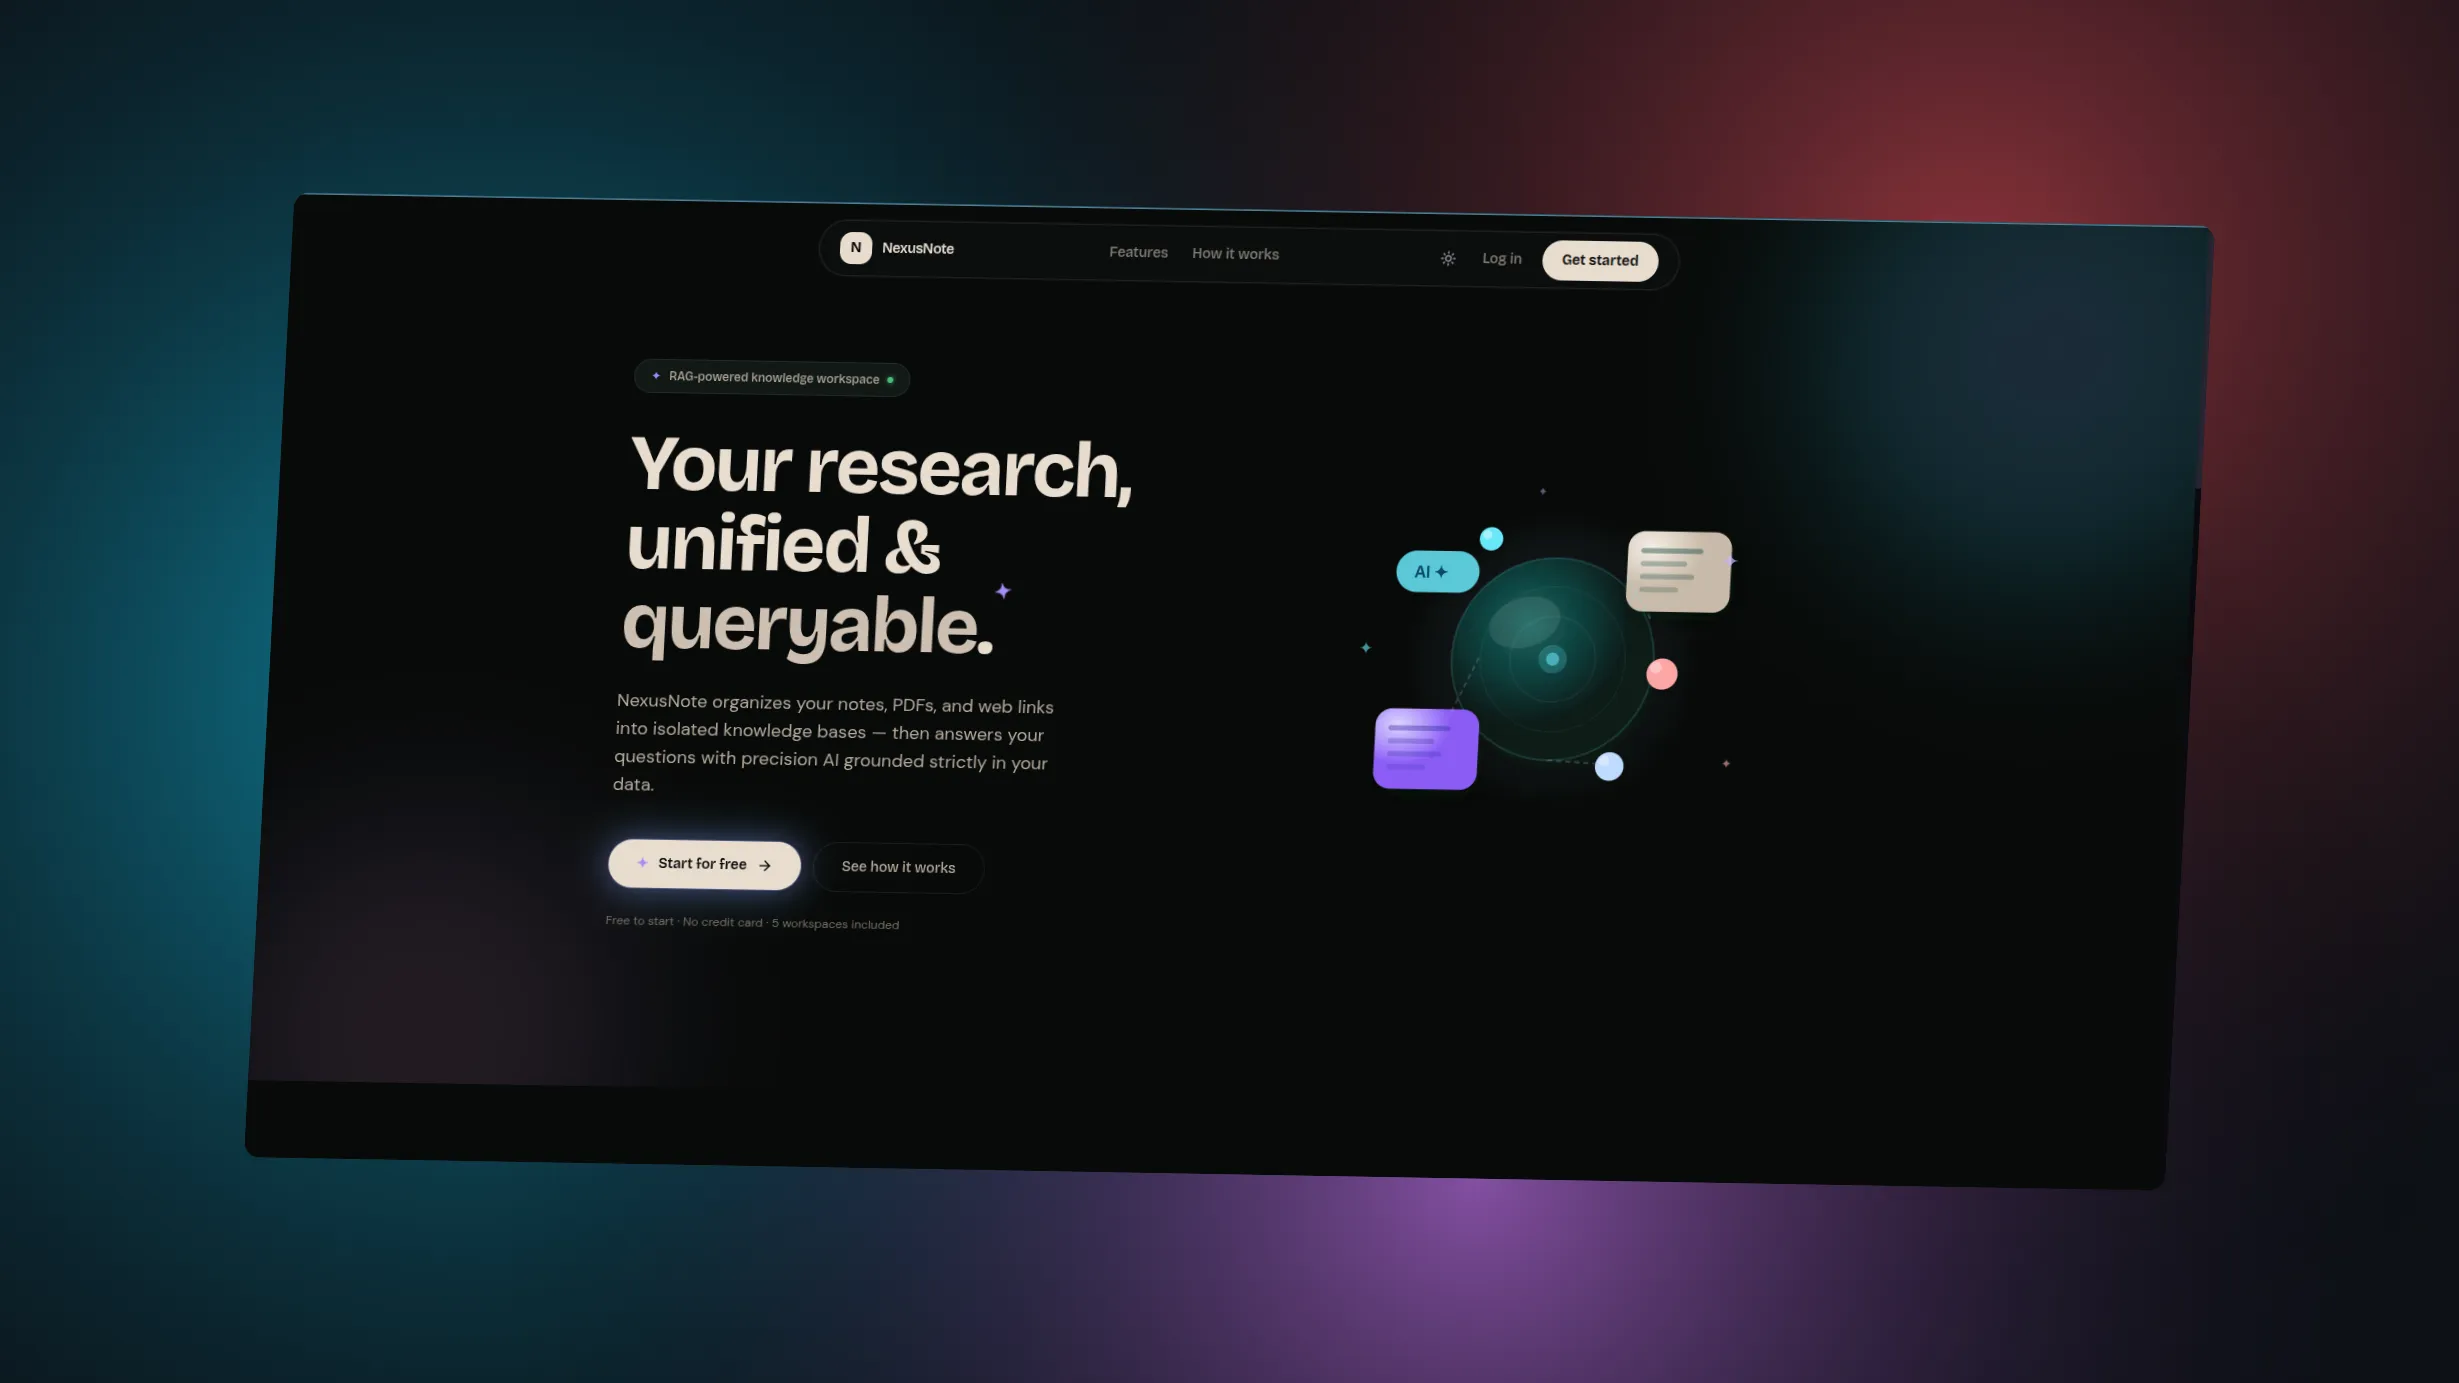
The problem
Research spread across notes, PDFs, and web links needs an AI assistant that answers only from the right workspace, with no leakage between them.
Who it is for
Students and knowledge workers.
What I built
A workspace-based knowledge app. Each workspace holds text notes, uploaded PDFs, and scraped links, and a RAG assistant answers only from that workspace's indexed content, using pgvector and Gemini. Next.js frontend, FastAPI backend.
Built with
- Frontend
- Next.js 14
- React
- TypeScript
- Tailwind CSS
- shadcn/ui
- TipTap
- TanStack Query v5
- Backend
- FastAPI
- Python
- SQLModel
- Alembic
- Data
- Neon Postgres
- pgvector
- AI
- Gemini 2.0 Flash
- text-embedding-004
- Integrations
- Cloudinary
- Google OAuth 2.0
- Infra
- Turborepo
In detail
- Source types: notes, PDFs, links
- 3
- Vector dimensions, pgvector
- 768
- Debounced note auto-save
- 1.5s
- Workspaces per user, API-enforced
- 5
Key features
Workspaces
Create, rename, and delete workspaces (max 5 per user). Workspace switcher in the top navbar with instant context switching; every login defaults to the most recently used workspace.
Notes
TipTap rich-text editor with Markdown persistence and debounced auto-save (1.5 s). Per-note "Create Embedding" indexes content into pgvector.
PDFs
Drag-and-drop upload stored on Cloudinary, text extracted server-side with pypdf, in-app PDF viewer via the Cloudinary URL. Deleting a PDF cascades removal of its vectors and the Cloudinary asset.
Links
Paste a URL and the server scrapes and stores the extracted text (httpx + BeautifulSoup). Per-link embedding with vector deletion on remove.
Embedding pipeline
FastAPI BackgroundTasks drives an async embedding worker per resource:
text chunked, embedded via Gemini text-embedding-004, vectors upserted
into Neon Postgres with pgvector. Job status streams to the frontend over
SSE.
AI assistant
Dedicated chat page per workspace with multiple named, persistent
sessions. Top-k vector similarity search filtered strictly by
workspace_id, responses grounded in retrieved chunks by
gemini-2.0-flash. Optimistic message UI with typing indicator and full
history persistence.
Auth and security
Email/password signup with JWT sessions (FastAPI + python-jose) plus
Google OAuth 2.0. Every route handler verifies
resource.user_id == current_user.id; all RAG queries include a hard
WHERE workspace_id = :workspace_id guard.
Design
Clean geometry, generous whitespace, subtle surface layering, and a
single violet accent (#6e6bff). Inter for UI, JetBrains Mono for code,
all colors through CSS custom properties. The landing page uses a Modern
Playfulism style: Cyprus and Sand palette, glassmorphism nav, claymorphism
hero orb, and bento-grid features.
Architecture
NexusNote is a Turborepo monorepo with two apps:
apps/web: Next.js 14 (App Router), TypeScript strict, Tailwind CSS, shadcn/ui, TipTap, TanStack Query v5.apps/api: FastAPI (Python, fully async), SQLModel (SQLAlchemy + Pydantic v2), Alembic migrations.
Embedding job flow
POST /embeddings/{resource_type}/{resource_id}
  → BackgroundTask enqueued
  → embedding_job row created (status = pending)
  → job_id returned to client

GET /embeddings/status/{job_id}  [SSE stream]
  → worker updates status: pending → processing → done | error
  → SSE handler polls DB row, emits events
  → frontend closes stream on done/error, updates UI
RAG query flow
user sends message
  → top-k vector search on document_chunks WHERE workspace_id = :id
  → retrieved chunks assembled as context
  → Gemini 2.0 Flash generates grounded response
  → assistant message persisted to chat_messages
  → response streamed back to client
Auth token flow
Access token stored in localStorage. On app mount, AuthProvider restores the token to axios headers and calls /session to validate.
Decision
OAuth token via URL fragment
Google OAuth redirects to /dashboard#accessToken=... and the SPA reads the
token from the fragment. Delivering the token this way avoids the CORS
problems of cross-origin cookie delivery between the FastAPI backend and
the Next.js SPA.
Data model
Five PostgreSQL tables plus pgvector:
users: email, hashed password, google_id.workspaces: owned by a single user; max 5 enforced at API layer.notes / pdfs / links: workspace-scoped content with extracted text fields.embedding_jobs: tracks pipeline status per resource.chat_sessions / chat_messages: persistent conversation history per workspace.document_chunks: single source of truth for all vectors:chunk_index,content,embedding vector(768),workspace_id,resource_type,resource_id.
Note
One vector table
Every chunk row carries workspace_id, resource_id, and resource_type,
so scoped retrieval and targeted deletion are plain SQL filters. No vectors
are stored anywhere else, and RAG context is assembled strictly from these
per-workspace chunks, never from raw content fields.
Outcome
NexusNote combines workspace-isolated vector search, a streaming embedding pipeline, and persistent AI chat in a Turborepo monorepo. Workspace isolation is enforced at both the query layer and the API boundary, and every feature runs against the real backend.
Challenges
- Strict workspace-scoped RAG with no cross-workspace vector leakage
- SSE-based embedding job status streaming from FastAPI BackgroundTasks
- TipTap Markdown serialization with debounced auto-save and no edit overwrite on re-render
- Atomic resource deletion cascading pgvector chunks and Cloudinary assets
- Google OAuth token delivery to Next.js SPA without CORS issues
What I learned
- pgvector similarity search with workspace-scoped WHERE filtering
- FastAPI BackgroundTasks driving an async embedding pipeline with SSE status
- TanStack Query v5 global 401 handler and optimistic UI updates
- Turborepo monorepo coordinating a Next.js frontend and FastAPI backend
- RAG context assembly strictly from per-workspace document chunks, never raw content fields
Have a role in mind?
Send me a message on X with the role and a link to the posting. My resume has the rest.