VeritasRAG
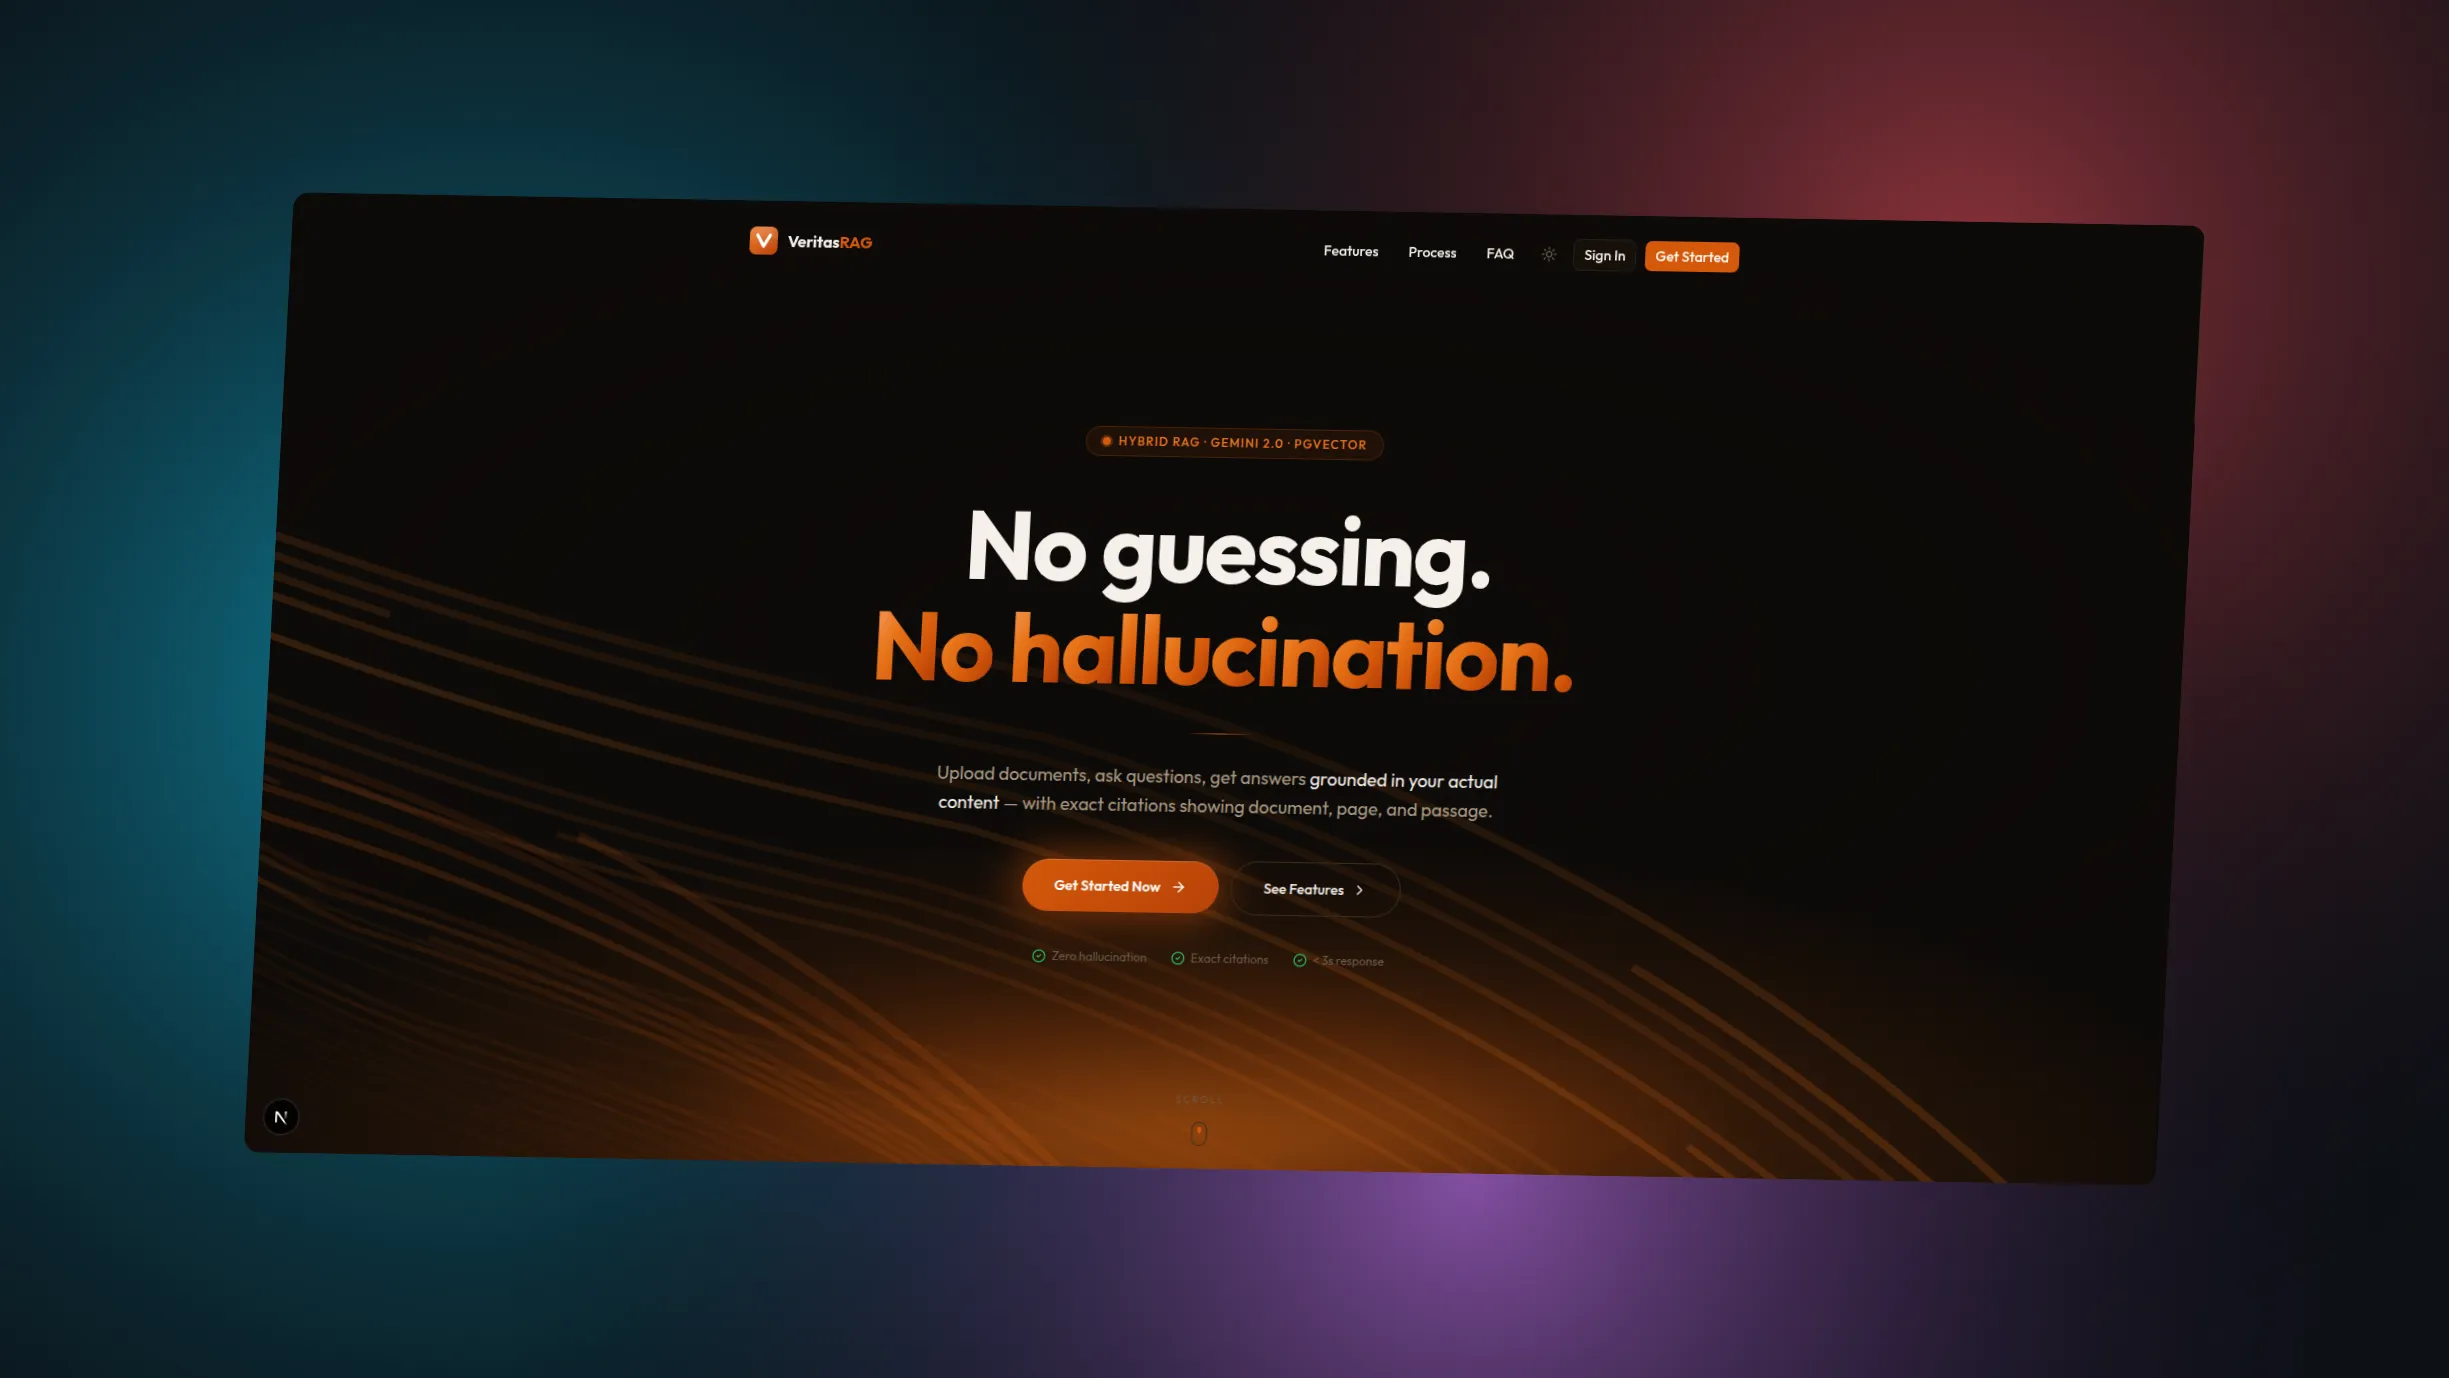
Upload PDF, DOCX or TXT files and ask questions about them. Answers cite their sources and come from hybrid vector search with Gemini.
- Status
- Live
- Role
- Full Stack Developer
- Team
- Solo
The problem
Answers about a document are only useful if they are grounded in the document and traceable back to it.
Who it is for
People who upload PDF, DOCX, and TXT files and want to ask questions about them.
What I built
A three-service RAG platform: a Next.js frontend, a Django backend for auth, documents, chat, and caching, and a FastAPI service that runs the RAG pipeline. Documents are chunked, embedded, and stored in pgvector. Queries use hybrid vector and BM25 retrieval with cross-encoder reranking, and Gemini answers with citations that include the page number and similarity score.
Built with
- Frontend
- Next.js 16
- React
- TypeScript
- Tailwind CSS
- shadcn/ui
- TanStack Query
- Backend
- Django 5
- FastAPI
- Python
- Celery
- Data
- PostgreSQL (Neon)
- pgvector
- Redis (Upstash)
- Cloudinary
- AI & Retrieval
- Gemini 2.0 Flash
- text-embedding-004
- ms-marco-MiniLM-L-6-v2
- BM25 + RRF
- Infra
- Docker Compose
- Vercel
- Render
In detail
- Independent services
- 3
- Chunk tokens / overlap
- 512 / 50
- HNSW vectors, pgvector
- 768-d
- Reranked candidates
- 20 to 5
Key features
Document management
Upload PDF, DOCX, TXT (max 50MB): the browser uploads directly to
Cloudinary via a Django-signed URL, so credentials never reach the client.
Celery tracks uploaded / processing / ready / failed status in
PostgreSQL, polled by the frontend every 3 seconds. Deleting a document
cascades chunks, embeddings, the Cloudinary asset, and related chat
messages atomically.
RAG pipeline
Extraction via pdfplumber, python-docx, or plain read. Sliding-window
chunking at 512 tokens with 50-token overlap preserving page numbers.
text-embedding-004 produces 768-dimension vectors stored in pgvector
with an HNSW index. Generation on gemini-2.0-flash with a strict
grounding prompt, streamed token-by-token over SSE.
Hybrid retrieval and reranking
pgvector cosine ANN (top-20) merged with PostgreSQL BM25 full-text search
(top-20) via Reciprocal Rank Fusion, then
cross-encoder/ms-marco-MiniLM-L-6-v2 reranks the merged set down to the
top-5 passed to generation.
Intent-aware retrieval
A single LLM call combines intent classification and HyDE to avoid a
redundant round-trip on factual queries. Ten intent categories, standalone
query rewriting for follow-up messages using conversation history, and
top_k tuned per intent: 20 for comparison/factual, 15 for
boolean/definition.
Citation grounding
Every answer ships citation cards with chunk text, source document, page
number, and similarity score. A per-answer grounding_score renders a
warning banner below 0.6, and if all top-5 similarities fall under 0.75
the response explicitly states the documents lack sufficient information.
Low-confidence queries are logged for admin review.
Chat interface
Named chat sessions scoped to one or more documents, progressive streaming render as SSE tokens arrive, a collapsible citation panel per answer, full session history in the sidebar, and per-message metadata: latency, retrieval score, cache hit/miss badge.
Redis caching (cache-aside)
Full RAG response cached by hash(question + doc_ids) for 1 hour,
retrieved chunks for 30 minutes, dashboard stats for 5 minutes, JWT
session data for 24 hours. Cache hits return in under 5ms, with the hit
badge visible in the UI and hit rate on the dashboard.
Auth, security, and observability
JWT access (15 min) and refresh (7 day) tokens set as
httpOnly; Secure; SameSite=Strict cookies exclusively by Next.js Route
Handlers. Every Django view enforces row-level ownership. Every query is
logged with latency, similarity, grounding score, cache hit, and model.
Health checks and a keep-alive ping warm Render cold starts.
Architecture
Three independently deployable services behind a Next.js BFF layer:
Browser
  └── Next.js 16 (Vercel)
        ├── Route Handlers (BFF): cookie management, auth proxy, SSE proxy, upload signature
        └── App Router pages: dashboard, documents, chat, citations

Next.js Route Handlers
  └── Django 5 (Render Web Service)
        ├── Auth: SimpleJWT signup/login/logout/refresh
        ├── Documents: CRUD, Cloudinary signature, status polling
        ├── Chat: session + message persistence, Redis cache-aside, SSE proxy
        ├── Stats: dashboard aggregates (Redis cached)
        └── Celery dispatcher → Redis broker

Celery Worker (Render Background Worker, same Django image)
  └── POST /ingest → FastAPI

FastAPI (Render Web Service, internal-only)
  ├── POST /ingest: extract → chunk → embed → pgvector write
  ├── POST /query: embed → hybrid search → rerank → generate → SSE stream
  └── GET /health

PostgreSQL + pgvector (Neon)  |  Redis (Upstash)  |  Files (Cloudinary)
Decision
Internal-only AI service
Django is the sole public-facing API. FastAPI enforces an X-Internal-Key
header on every endpoint and only Django calls it, so the entire RAG surface
is unreachable from the internet and auth lives in exactly one place.
Tradeoff
512MB RAM budget
The ~80MB cross-encoder reranker loads once at FastAPI startup and has to
fit alongside the app inside Render's free-tier 512MB limit, which shaped
model choice (ms-marco-MiniLM-L-6-v2) and ruled out larger rerankers.
Ingestion flow
POST /api/documents/ (Django)
  → DOCUMENT record (status = uploaded)
  → Celery task dispatched

Celery: process_document(document_id)
  → FastAPI POST /ingest {document_id, storage_key, file_type}
  → fetch file from Cloudinary
  → extract text → chunk (512t, 50 overlap) → embed (text-embedding-004)
  → write CHUNKS + EMBEDDINGS to pgvector
  → return {chunk_count}
  → DOCUMENT.status = ready
Query flow
user sends message
  → Django: Redis cache check hash(question + doc_ids)
  → cache hit: return in <5ms
  → cache miss: FastAPI POST /query (httpx streaming)
      → embed question (text-embedding-004)
      → pgvector HNSW ANN top-20 + BM25 FTS top-20
      → Reciprocal Rank Fusion merge
      → cross-encoder rerank top-20 → top-5
      → grounding check: all scores < 0.75 → grounding_score = 0.0
      → grounding prompt + gemini-2.0-flash SSE stream
  → Django proxies SSE → Next.js Route Handler → browser
  → on complete: persist MESSAGE + CITATIONS + QUERY_LOG; cache response
Note
RRF scores are not similarities
Reciprocal Rank Fusion produces scores around 0.016, on a different scale from cosine similarity. Grounding thresholds (0.75) are therefore checked against the raw ANN similarities, never the fused rank scores.
Data model
Eight PostgreSQL tables plus pgvector:
users: UUID PK, email, hashed password, full name.documents: user-owned; filename, storage_key, file_type, status, chunk_count.chunks: document-scoped; chunk_index, content, token_count, page_number.embeddings: one-to-one with chunks;vector(768), model_name. Kept separate so re-embedding with a new model doesn't touch chunk data.chat_sessions: user-owned; title, document_ids (jsonb array).messages: session-scoped; role, content, retrieval_score, grounding_score, latency_ms, cache_hit.citations: message-scoped; chunk_id FK, similarity_score, citation_order.query_logs: one observability row per query: question, latency, grounding score, cache hit, model used, low_confidence flag.
Outcome
VeritasRAG combines hybrid vector and keyword retrieval, cross-encoder reranking, intent-aware query routing, streaming SSE generation, multi-layer Redis caching, and strict citation grounding across three Docker-based services. Every answer traces to an exact source chunk with page-level provenance, and each architectural boundary is enforced at both the API and database layers.
Challenges
- Proxying SSE stream from FastAPI through Django and a Next.js Route Handler to the browser without buffering or timeout
- Hybrid ANN + BM25 reciprocal rank fusion where RRF scores (~0.016) must not be compared against cosine similarity thresholds
- Cross-encoder reranker (~80MB) loaded at FastAPI startup within Render free-tier 512MB RAM constraint
- httpOnly JWT cookies set exclusively via Next.js Route Handlers: no token ever reaches browser JavaScript
- Atomic document deletion cascading Celery ingestion status, pgvector chunks, embeddings, and Cloudinary asset in one transaction
- Intent-aware retrieval routing: combined intent classification + HyDE in a single LLM call with standalone query rewriting for follow-up messages
What I learned
- pgvector HNSW cosine ANN combined with PostgreSQL BM25 full-text search via reciprocal rank fusion for higher recall on technical documents
- Cross-encoder reranker (ms-marco-MiniLM-L-6-v2) scoring merged top-20 candidates down to top-5 before generation
- FastAPI internal-only architecture: Django is the sole public-facing API; FastAPI enforces X-Internal-Key on every endpoint
- Celery async ingestion pipeline decoupling upload from extract, chunk, embed, and pgvector write
- Redis cache-aside at three layers: full RAG response (1h), retrieved chunks (30min), dashboard stats (5min)
- Grounding score threshold gating: explicit low-confidence warning when top similarity scores fall below 0.75
Have a role in mind?
Send me a message on X with the role and a link to the posting. My resume has the rest.